A faster service tier for the same model
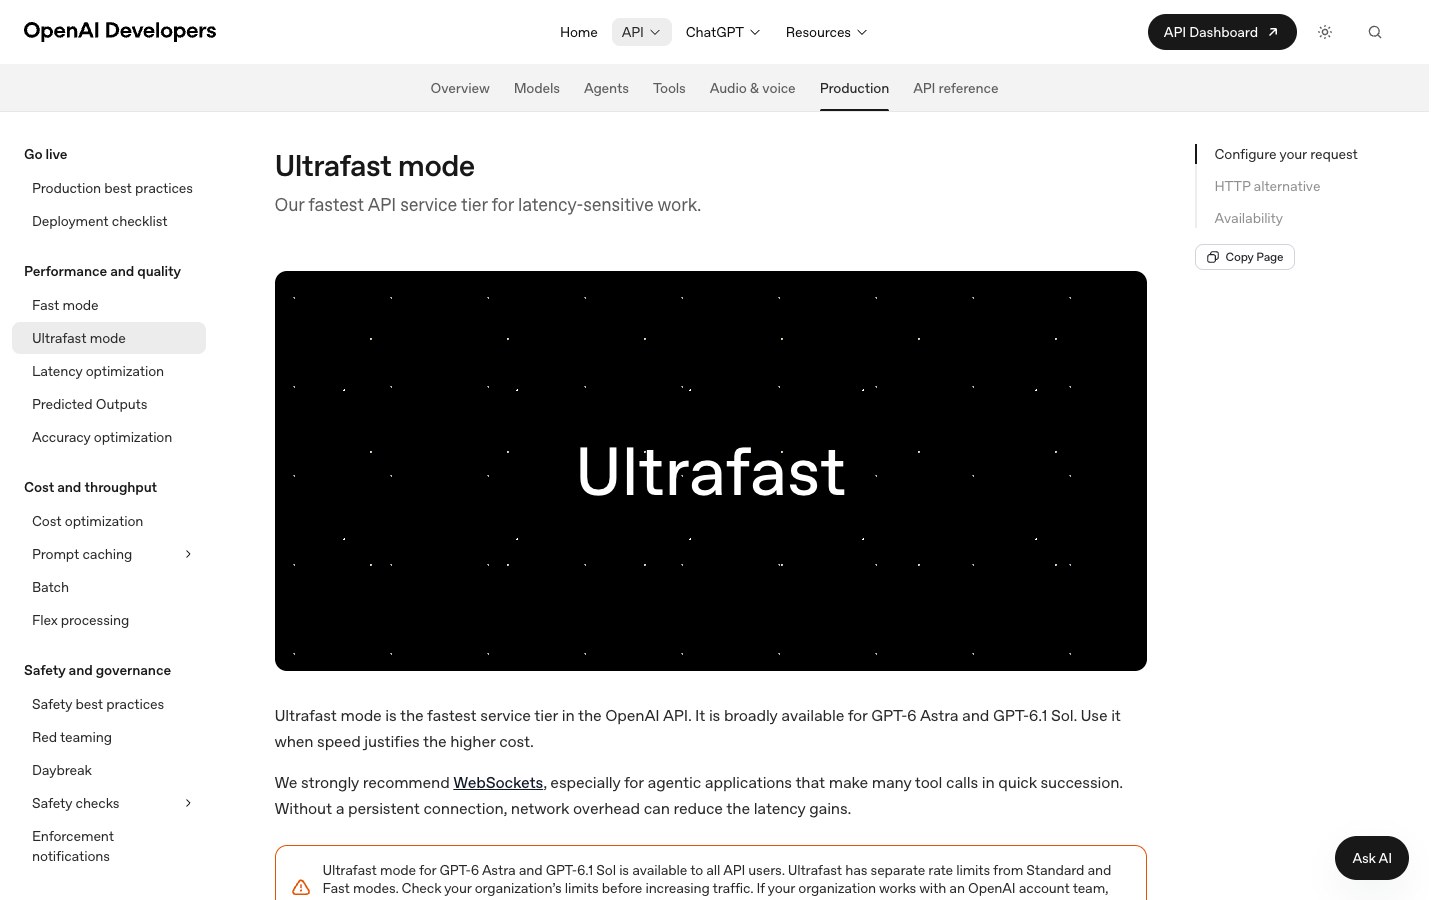
OpenAI has added GPT-6.1 Sol to Ultrafast in the API. Its October 8 announcement lets developers request the faster generation tier. This still uses the same model, rather than announcing a separate model or an automatic improvement in answer quality.
Faster generation can help workflows with many consecutive responses. It does not necessarily accelerate an external search, a download or a tool waiting for another service. Those steps also contribute to the time a complete task takes.
API token rates are six times higher
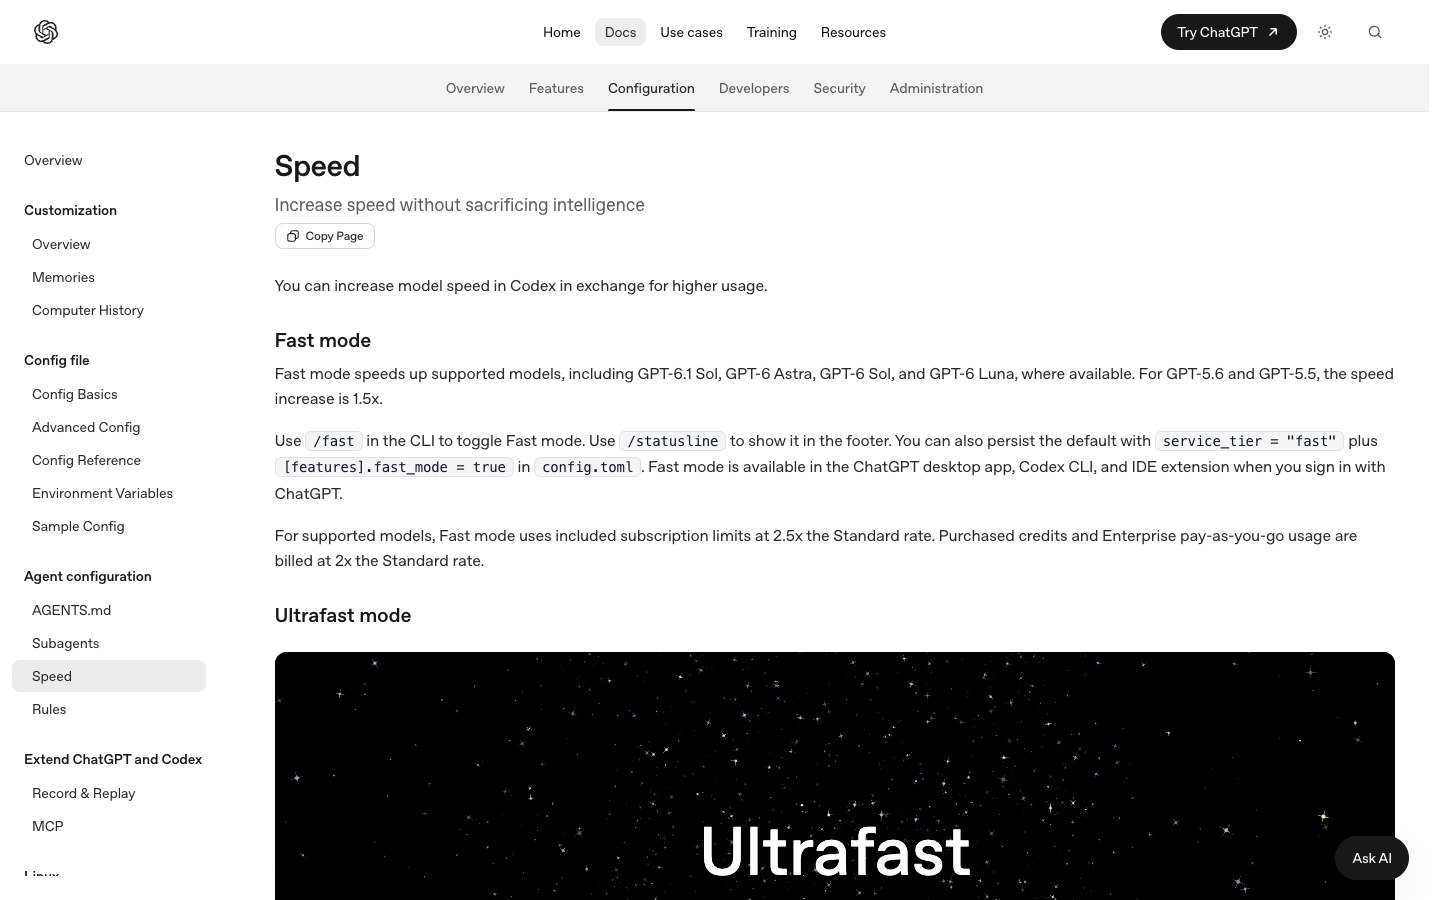
For inputs of up to 272,000 tokens, OpenAI’s pricing table lists Sol Ultrafast at $12 per million input tokens and $60 per million output tokens. The comparable standard rates are $2 and $10. Both token rates are therefore six times higher. These are API usage charges, separate from subscription pricing.
Tokens measure the text processed and generated by the service. Longer inputs have different rates, and regional processing options can add a surcharge. Check both token usage and the time your application needs to save before enabling the tier throughout a project.
Subscription access has separate requirements
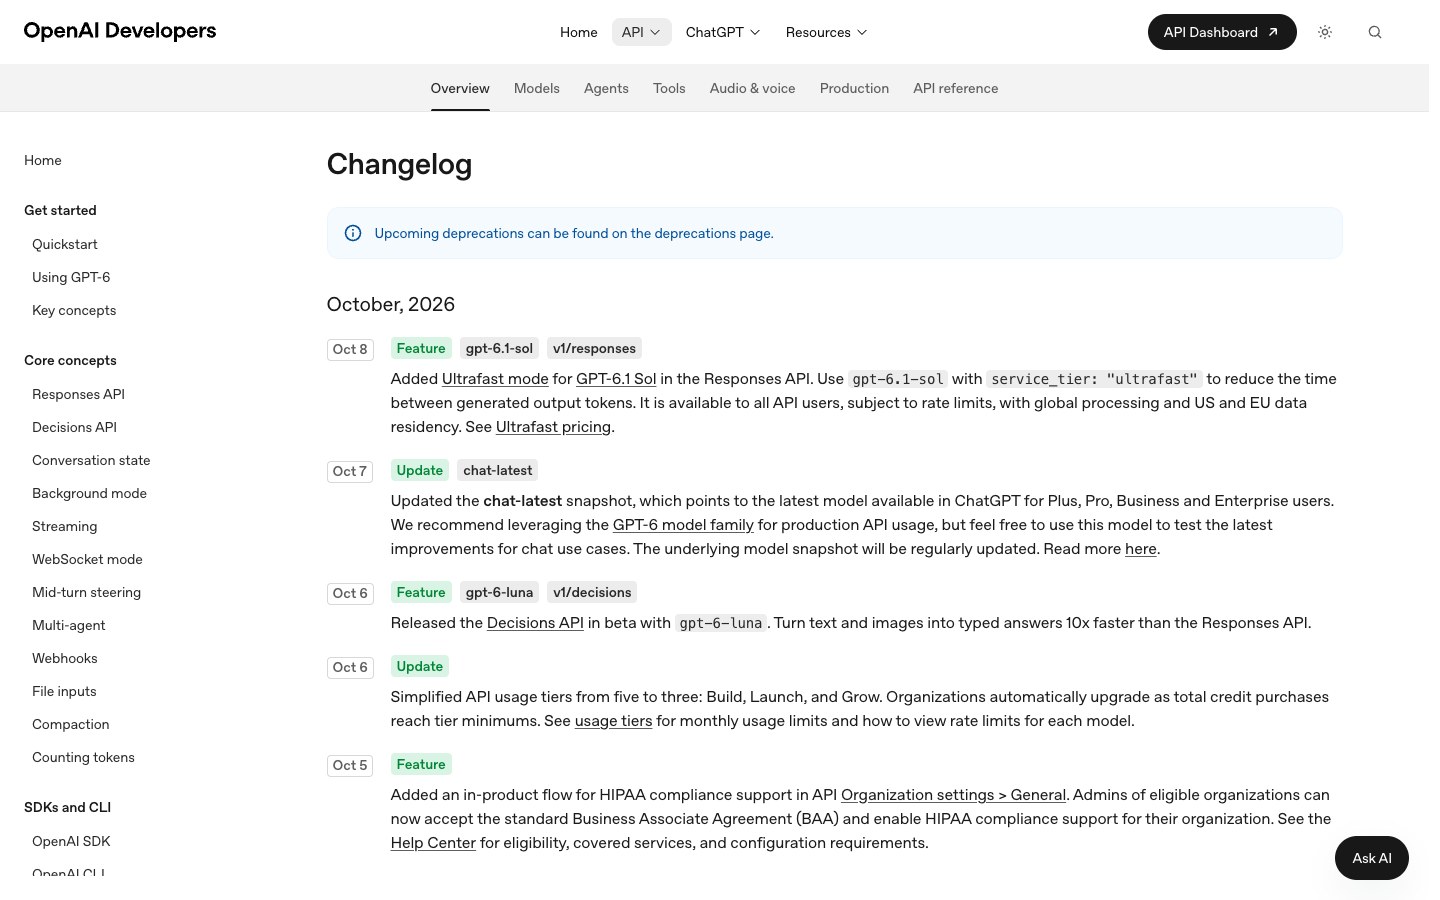
The Codex and ChatGPT Work changelog makes Sol Ultrafast available to the $500 Pro plan and eligible Enterprise and Edu accounts. Enterprise workspace owners must enable it. That subscription availability is separate from developer API access and does not announce inclusion in every ChatGPT plan.
If repeatedly sending long instructions is your main expense, context caching addresses a different part of the bill. Compare faster service tiers and reusable context against the cost and runtime of the same workload.
The conversation starts here
Sign in with a supporter account to comment. Sign in
Nobody has commented yet. Want to go first?