An AI system built by Microsoft reached the right diagnosis in 83.2% of 304 notoriously hard clinical cases drawn from the New England Journal of Medicine, according to a study published October 22, 2026, in Science. Generalist physicians working the same cases got 36.1% right. The system is called MAI-DxO, and the paper's authors are Microsoft researchers, including Mustafa Suleyman, who runs Microsoft AI.
The test was a computer simulation built from cases that had already been published, and the doctors each worked alone, with no specialists involved. MAI-DxO has not yet seen a single real patient. That comes next, at Beth Israel Deaconess Medical Center in Boston.
A panel of virtual doctors
MAI-DxO is software that directs an existing language model, the kind of AI behind chatbots, such as OpenAI's GPT-5, to work through a case the way a small team of physicians would. Microsoft calls it an orchestrator: the medical knowledge comes from the model, and MAI-DxO splits the job among several AI agents, copies of the model that each get one task, then coordinates what they decide.
The 2025 preprint of the study describes five roles, all played by the same model. One keeps a ranked list of the three most likely diagnoses and revises it with every new finding. Another picks the tests that best tell those possibilities apart. A third plays devil's advocate, hunting for evidence against the favorite so the team doesn't lock onto its first idea. A fourth watches spending and suggests cheaper tests when they would do the same job, and a fifth checks that every request makes sense.
After each round of discussion, the panel can ask the patient a question, order a test or commit to a diagnosis. When it orders bloodwork or a scan, it gets the result back and the debate starts again.
How the test worked
The NEJM cases are real patient histories that once stumped their doctors, published along with the final diagnosis. Microsoft turned them into an interactive benchmark called SDBench. Whoever is diagnosing starts with a short summary, such as the patient's age and why they came in, and has to ask for everything else.
Those questions and orders are answered by a separate AI model that holds the full case file and plays both patient and lab. It hands over only what a doctor would get from that question or test, with no hints or interpretation. A third model acts as judge, checking the final answer against the published diagnosis. Multiple-choice exams can't capture this, since they give you every fact up front, while a real workup means deciding what to look for. Microsoft has released part of SDBench so other teams can test their own systems the same way.
The study also added a set of more ordinary cases: patients admitted through the emergency department, taken from MIMIC-IV-ED, a database of real ER visits at Beth Israel Deaconess. There, MAI-DxO scored 80.3% and the physicians 46.8%.
Which doctors it was up against
The human side was made up of primary care doctors and general internists, each working solo, TechCrunch reports. There were no specialists or care teams, who are the people who usually handle cases this complex in a hospital. Microsoft gives two numbers for the physicians: 22% correct with no outside help and 36% when they could use textbooks and the internet. So the AI's 83.2% is more than double the score of doctors with references and nearly four times that of doctors without them.
In the 2025 version, the comparison involved 21 physicians in the US and UK with a median of 12 years in practice, who were barred from asking colleagues or using search engines or other AI tools. That ban on search engines doesn't quite square with Microsoft's new 36% figure for doctors using the internet, and neither Microsoft nor TechCrunch says whether the group or the rules changed for the version Science has now published.
What the workup costs
Every question and test carries a simulated price, since a system that gets the right answer by ordering everything would be useless in a real hospital. In the 2025 version, each round of questions cost $300, and tests were priced using the 2023 rate sheet of a large US health system. Those aren't anyone's actual bills, but they let the AI and the doctors be scored against the same yardstick.
According to the figures TechCrunch reports, GPT-5 on its own solved 78.9% of the hard cases and ran up about $8,400 in tests per case. Under MAI-DxO, it spent about $3,000 less per case, roughly $5,400, and was right about four points more often. Microsoft says no other approach, human or AI, was both more accurate and cheaper than MAI-DxO on both sets of cases.
How much credit goes to the model
TechCrunch's reading of the study's own numbers is that the underlying model matters more than the panel. On its own, GPT-5.5, released in April 2026, solved 72% of the hard cases. Google's smaller Gemini 2.5 Flash fell short of that even with the panel's help, which lifted it from 46.4% to nearly 69%. The panel did help GPT-5.5 on the hard cases, taking it to nearly 87%, but on the ER cases it scored around 85% with or without MAI-DxO.
Microsoft's researchers say the gains naturally shrink as a model approaches a perfect score. If TechCrunch's reading holds, a hospital weighing this kind of tool should care more about the model underneath than about how it's organized.
What the study doesn't show
NEJM cases are chosen because they are rare and instructive. Doing well on them says little about how MAI-DxO would handle back pain or an ordinary fever, a patient with missing records, or someone who gets worse within the hour. Microsoft acknowledged in 2025 that it still needed to test the system on everyday presentations.
No one outside Microsoft has checked the results yet. The authors are Microsoft researchers, including Suleyman and the company's chief scientific officer, Eric Horvitz, and the system isn't cleared for clinical use. The paper itself says the findings come from a controlled benchmark setting.
Microsoft pitches MAI-DxO as a decision-support tool that suggests diagnoses and tests for a clinician to review, with the doctor still making the call. Spanish bioinformatics pioneer Alfonso Valencia has already pushed back on DeepMind's promise to cure every disease within a decade, arguing that AI's medical advances need perspective.
Next up: real patients in Boston
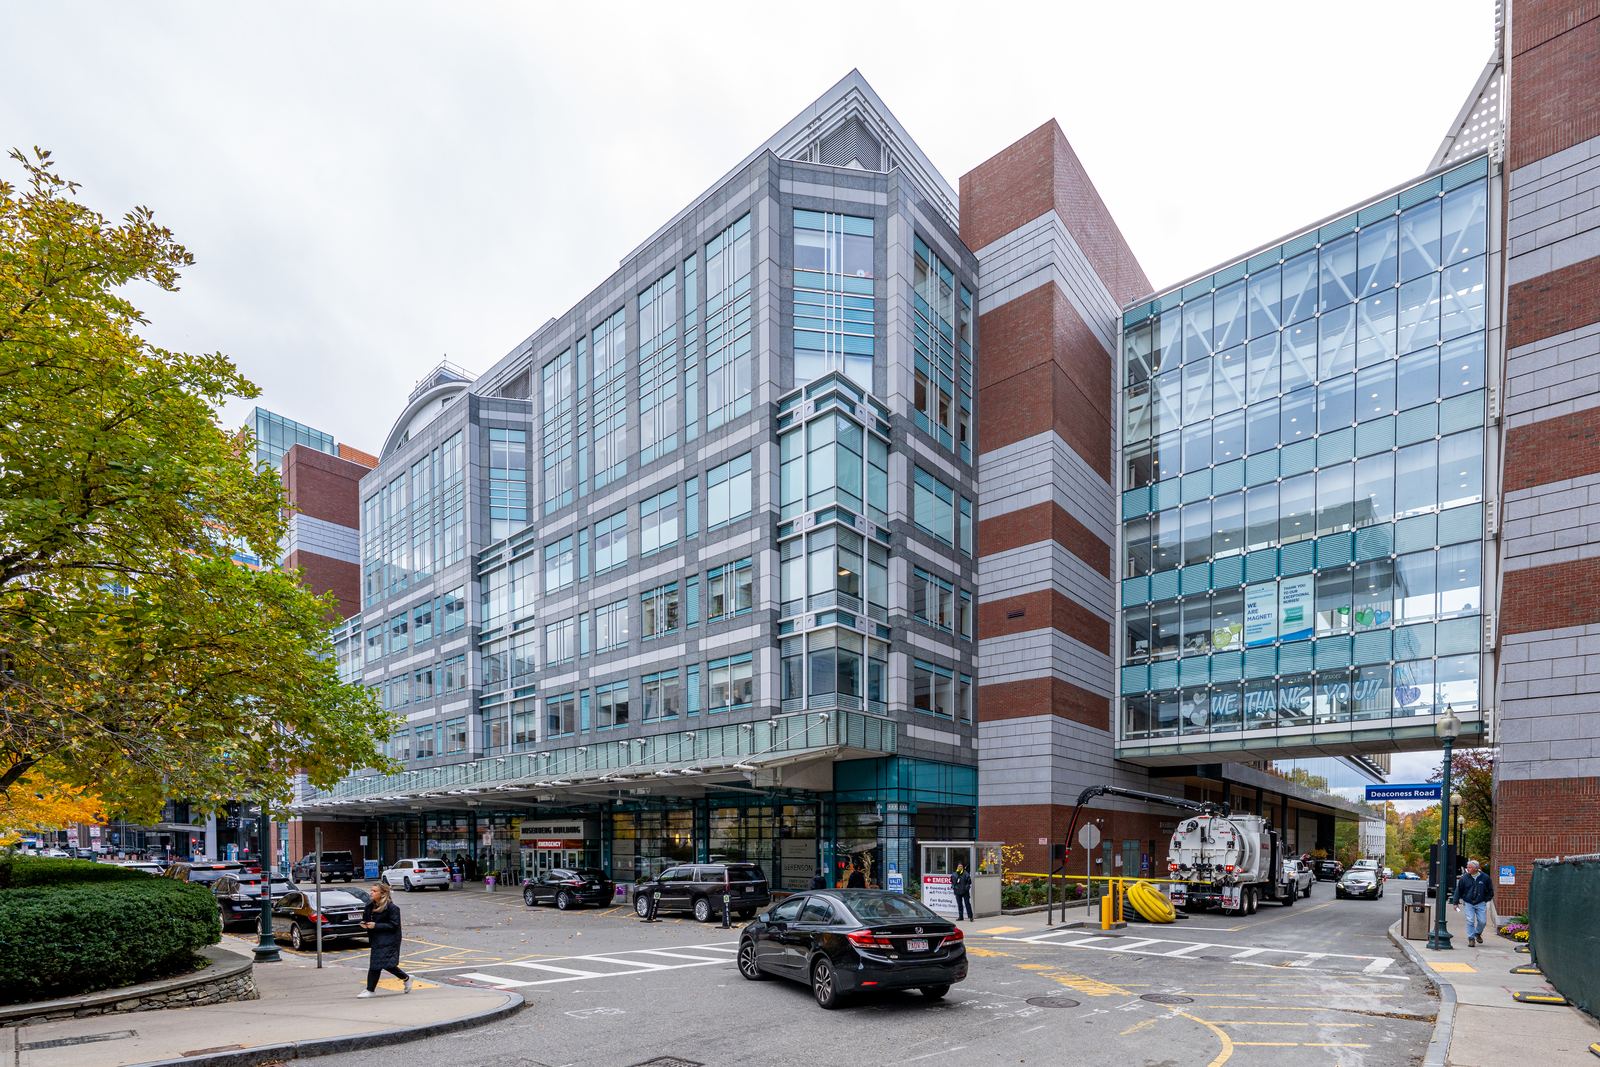
Microsoft will test MAI-DxO at Beth Israel Deaconess in a prospective study, meaning with patients as they arrive rather than with closed cases. Everyone will get their usual care. Patients who agree to take part will also talk to the system, and its recommendations will be compared with what their doctors decided.
Suleyman frames the result as a step toward what Microsoft calls medical superintelligence, and he expects health models to get "an order of magnitude better" within 24 to 36 months. Google is working on a similar system called AMIE, and OpenAI already offers ChatGPT Health to help people make sense of their lab results. Microsoft is also training a healthcare model with Mayo Clinic that it plans to release in 2027.
The conversation starts here
Sign in with a supporter account to comment. Sign in
Nobody has commented yet. Want to go first?